
Contents
I. Optimization Steps
We can compare the code optimization process of MicroPython to "the steps to speed up a bicycle": first identify the core reasons why the bicycle runs slowly (such as flat tires or a laggy chain), then start with simple adjustments (inflating tires, lubricating the chain), and finally consider replacing high-end parts (lightweight frame, carbon fiber wheels). The code optimization of MicroPython also follows the order of "from simple to complex, from software to hardware", which can achieve the maximum performance improvement at the lowest cost and avoid wasting time by getting bogged down in complex low-level optimization from the very beginning.
Before starting the optimization, let's first understand several core basic concepts:
- Timing Tools (utime Module): A time processing module specifically designed by MicroPython for embedded systems.
utime.ticks_us ()can obtain a microsecond-level system timestamp (1 microsecond = 1/1000 millisecond = 1/1000000 second),and utime.ticks_diff ()is used to calculate the difference between two timestamps. This is more suitable for embedded scenarios than the ordinarytimemodule, since embedded development often requires high-precision timing at the millisecond/microsecond level. - Decorator (the @ symbol): a syntactic sugar in Python that can, without modifying the code of the function itself, add extra functionality to a function (such as the timing function here). It is just like wrapping a gift with wrapping paper: the gift itself remains unchanged, but it gains an extra decorative effect, and decorators make code more reusable.
- native/viper code emitter: A dedicated compile tool for MicroPython (extension: This is a key optimization feature that distinguishes MicroPython from standard Python):
- native emitter: compiles Python code into native machine code for microcontrollers, runs several times faster than MicroPython bytecode, and is compatible with almost all Python syntax.
- viper emitter: A more aggressive compiler than native, which supports direct manipulation of hardware registers, boasts an execution speed close to that of the C language, yet comes with certain syntax restrictions (e. g., only basic data types are supported).
- Hardware-specific optimization: Utilize hardware peripherals of the microcontroller (such as DMA (Direct Memory Access), hardware PWM, hardware SPI) to replace software simulation operations (extension: this is the optimization method that brings the greatest efficiency improvement; for example, software-simulated SPI can only transmit several thousand times per second, while hardware SPI can reach millions of times per second).
- mpy-cross (MicroPython cross-compiler): The official cross-compilation tool for MicroPython, which can pre-
. pyscripts into. mpybytecode files on a personal computer (PC), and then upload the. mpyfiles to a microcontroller for execution. Compared with dynamically compiling. pyfiles on the device, pre-compiled. mpybytecode has three advantages: it reduces the compile time on the device (especially when running a script for the first time, preventing the device from wasting computing power on compiling);. mpyfiles are smaller in size, saving flash memory space on the microcontroller;Bytecode loads and executes slightly faster than the original. pyfiles.
The process of developing high-performance code consists of the following phases, which shall be executed in the listed order:
- Identify the slowest parts in the code (profiling): This is the first and most critical step of optimization — if you optimize blindly, you may spend a lot of time optimizing code that is already fast, which is completely meaningless. We use the timing feature of the
utimemodule to measure the execution time of each function and find the "performance bottleneck" that takes the longest time. - Improving the Efficiency of Python Code (Basic Optimization): Without changing the execution logic of the code, optimize the writing style of Python code (for example, using list comprehensions instead of for loops, using local variables instead of global variables — local variables are accessed faster in MicroPython, reducing unnecessary function calls, etc.). This step is the simplest and can solve most performance problems.
- Use the native code emitter (intermediate optimization): If performance is still insufficient, use MicroPython's
@micropython.nativedecorator to compile the function into native machine code, which will significantly improve execution speed with almost no code modifications required. - Use the Viper code emitter (advanced optimization): if the code is still not fast enough after being natively compiled, use the
@micropython.viperdecorator, which can make the code execution speed close to that of C language, but note that there are syntax restrictions (for example, complex Python data structures cannot be used). - Use mpy-cross to compile into bytecode (pre-compilation optimization): If the loading time of the script on its first run is still long after the previous optimizations (especially for large scripts), use mpy-cross on your computer to pre-
. pyfiles into. mpybytecode files and then upload them to the device. This step does not require modifying the code, only changes the file loading method, and can significantly reduce the compilation overhead on the device. - Use hardware-specific optimization (ultimate optimization): This is the final step, which utilizes the hardware peripherals of the microcontroller to replace software simulation, such as using hardware DMA to transmit data and hardware timers to replace software delays. This is the ultimate solution for improving performance.
II. Optimization Methods
2.1 Identify the slowest code
When identifying the slowest code sections, we can usually establish function groups recorded in ticks through the judicious use of timing utime. Code execution time can be measured in ms (milliseconds), us (microseconds), or CPU cycles.
You may add the following @timed_function decorator to time any function or method:
import time

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func
Here, we use the mpremote tool to connect to the Raspberry Pi Pico, copy the above code into the REPL, and press Enter to execute (at this point, the decorator has been defined):
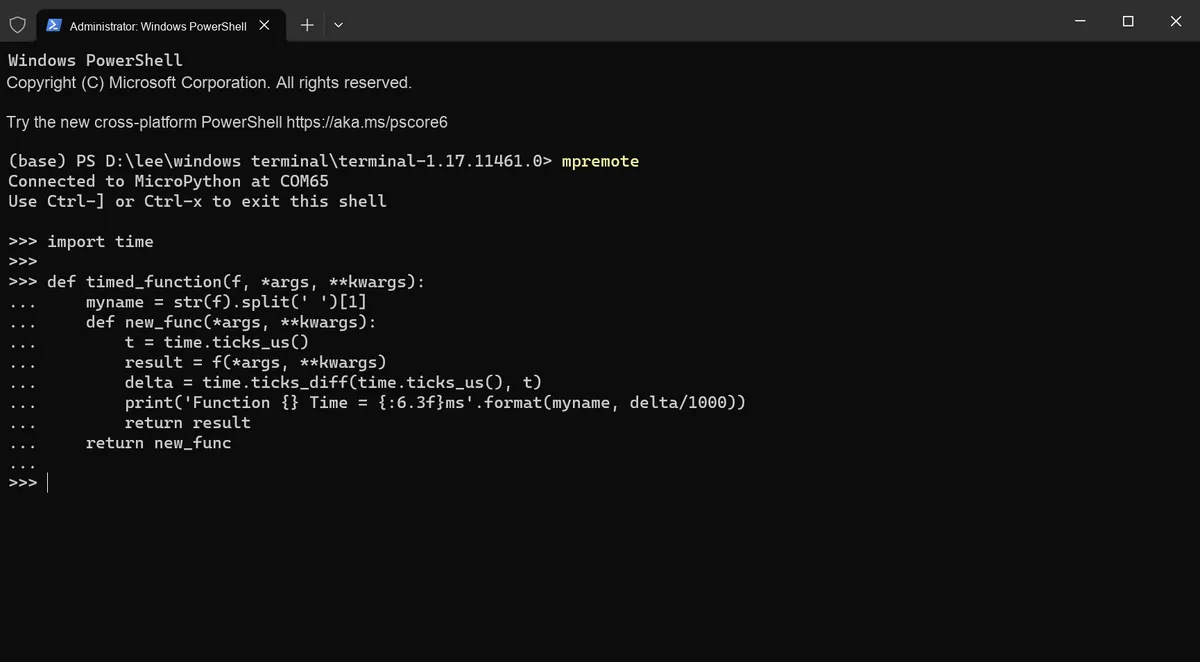
Next, define a test function (to simulate time-consuming operations):
# Decorate the test function with the @timed_function decorator
@timed_function
def slow_function():
    for i in range(10000):
        pass
    return "Done"
We paste it into the REPL:
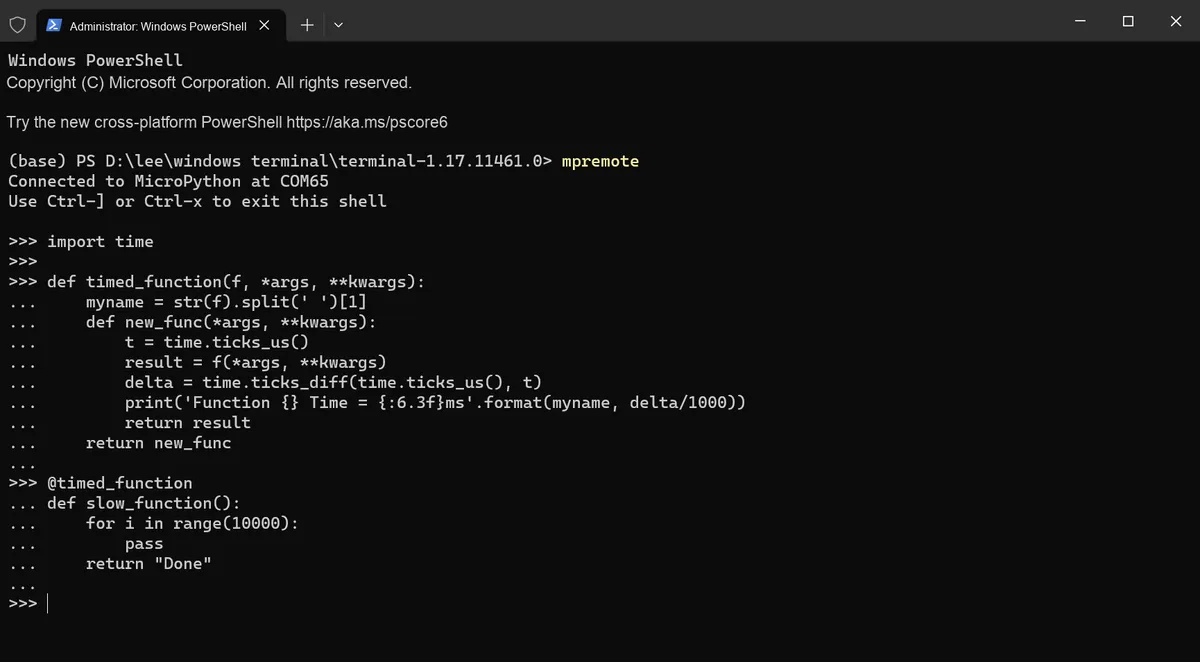
Then call the function and check the timing result:
slow_function()We can see that the time-consuming result of the function execution has been output:
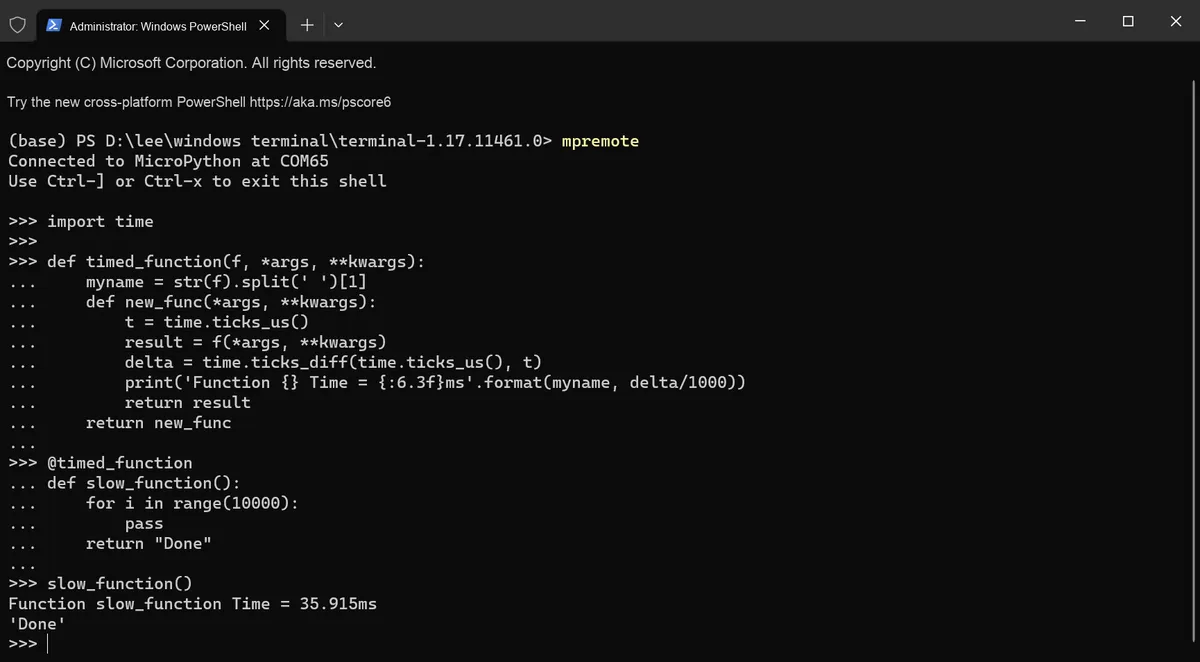
2.2 Specific Measures for Performance optimization
2.2.1 Performance Bottlenecks and Core Basic Concepts of MicroPython
2.2.1.1 Core Basic Concepts
2.2.1.1.1 Variables and Constants
Here, first we need to understand the difference between variables and constants, which is the foundation of programming; the core difference between the two lies in when their values are determined:
- Variable: A variable is dynamically assigned at runtime and its value can be changed. When MicroPython accesses a variable, it needs to look it up in the global or local dictionary, which incurs a small amount of overhead — this overhead will be amplified especially when the variable is accessed frequently in a loop.
# Variable, stored in a dictionary at runtime
max_count = 10000
for i in range(max_count):
    # The value of max_count is looked up in the dictionary on every iteration
pass - Constants have values determined at compile time and cannot be modified. MicroPython provides the
const ()declaration (similar to C's#define), which directly replaces the identifier with the literal value when compiling bytecode, thus completely eliminating runtime dictionary lookup overhead.
from micropython import const
# Constant, replaced directly with 10000 at compile time
MAX_COUNT = const(10000)
for i in range(MAX_COUNT):
    # 10000 is used directly in the loop, no dictionary lookup needed
    pass
2.2.1.1.2 Three Memory Partitions
Embedded microcontrollers (such as the RP2040) have extremely limited memory resources (for example, only 264KB of RAM), and the object storage of MicroPython directly relies on memory partitioning, where heap allocation and deallocation represent the biggest performance bottleneck. We use the metaphor of "Warehouse Management" to understand the three partitions:
| Memory Region | Analogy (Warehouse) | Stored Content | Characteristics (Performance-Related) |
|---|---|---|---|
| Static area | Fixed shelves for long-term storage (permanent) | Global variables, static variables, program code, constants | No allocation / reclamation overhead; lifetime matches the program |
| Stack | A small shelf for temporary pick-ups (fast) | Local variables, function parameters, return addresses of function calls | Allocation / release is extremely fast (hardware-level), but space is very small (a few KB) |
| Heap | A miscellaneous area for temporary piles (messy) | Dynamically created objects (lists, dicts, byte arrays, class instances) | Allocation / reclamation has significant overhead and is prone to fragmentation |
For memory management in embedded development, we often face the following several difficulties:
- Heap allocation requires traversing free memory blocks, which is time-consuming;
- Objects that are no longer used in the heap require garbage collection (GC) for cleanup, a process that blocks the program and takes several milliseconds — which is fatal in real-time scenarios;
- The stack space is limited. If there are too many local variables or too deep function nesting, a stack overflow (direct crash) will be triggered.
2.2.1.1.3 References and Copies
A reference is essentially the "house number" of an object (analogous to a shortcut on a computer). A variable does not store the data itself, but rather the memory address of the data. Manipulating a reference does not copy the data, so it has extremely low overhead.
# Create a bytearray object on the heap; a stores the object's address (like a house number)
a = bytearray(10)
# b is a reference to a, pointing to the same object, no new allocation
b = a
# Operating on b changes the content of a, because they are the same object
b[0] = 1
# Output: 1
print(a[0])
In the terminal, the running result is as follows:
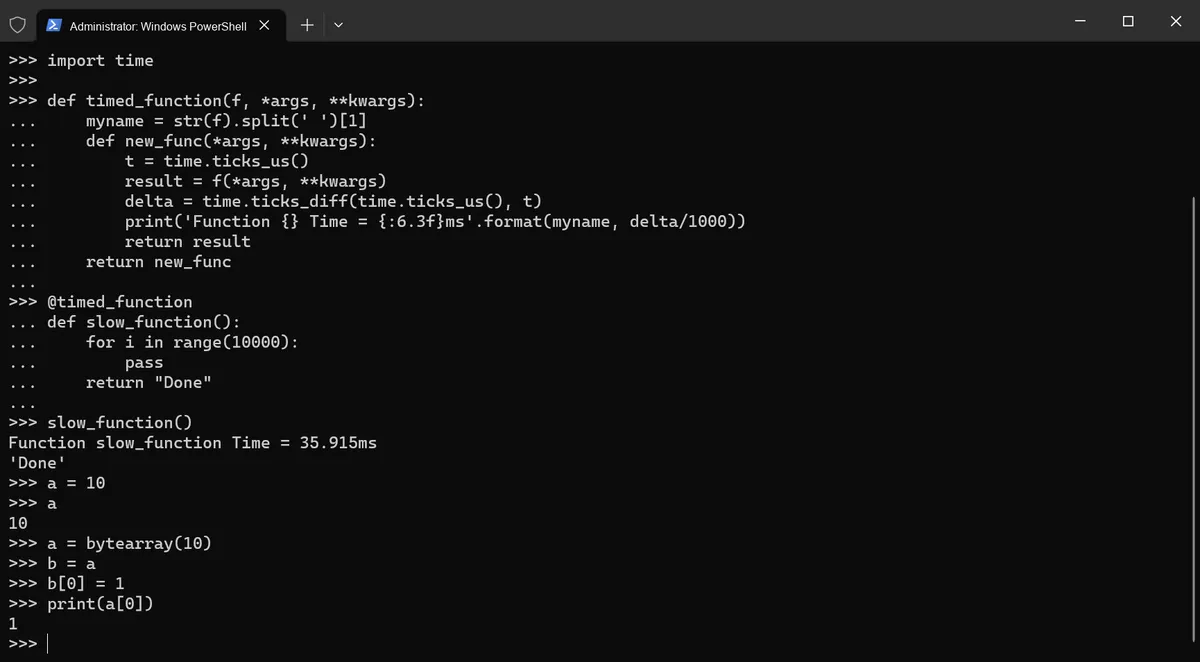
Then for copying (here referring to deep copy; we won't go into excessive detail about the difference between shallow copy and deep copy), it will replicate the entire data, create a new object on the heap, and store a new data set, which comes with extremely high overhead (especially for Big data):
# Large bytearray (10KB on the heap)
a = bytearray(10000)
# Slicing creates a new bytearray (~2KB on the heap), which is a deep copy
b = a[30:2000] 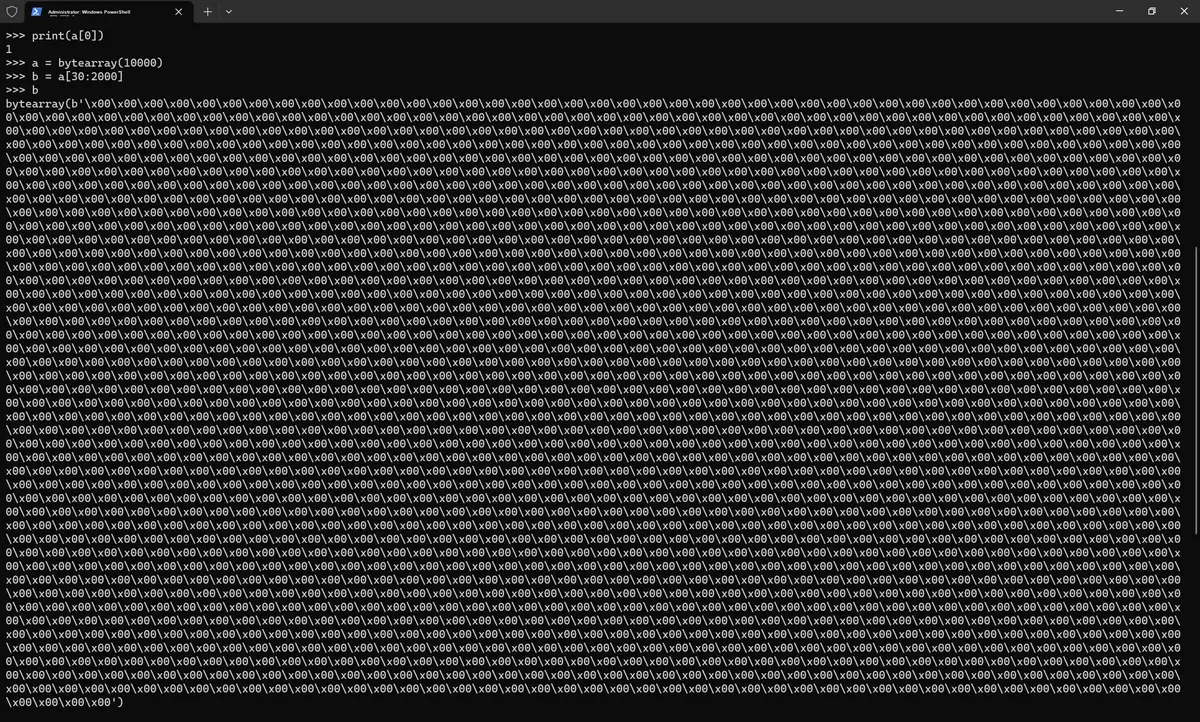
To avoid excessive heap allocation caused when copying large byte arrays, we can use memoryview, a shallow reference tool provided by MicroPython. Essentially, it acts as a "read/write access pointer" to buffer objects (such as byte arrays, arrays, and bytes). When slicing, it does not copy data but only passes the address, thus completely eliminating heap allocation.
# Large bytearray
a = bytearray(10000)
# Create a memoryview (allocates only a small object, a few dozen bytes)
mv = memoryview(a)
# Slice memory view, no new allocation, only passes the address
b = mv[30:2000]
# Operating on b changes the contents of a, because it is the same data
b[0] = 1
print(a[30])
The running results are as follows:
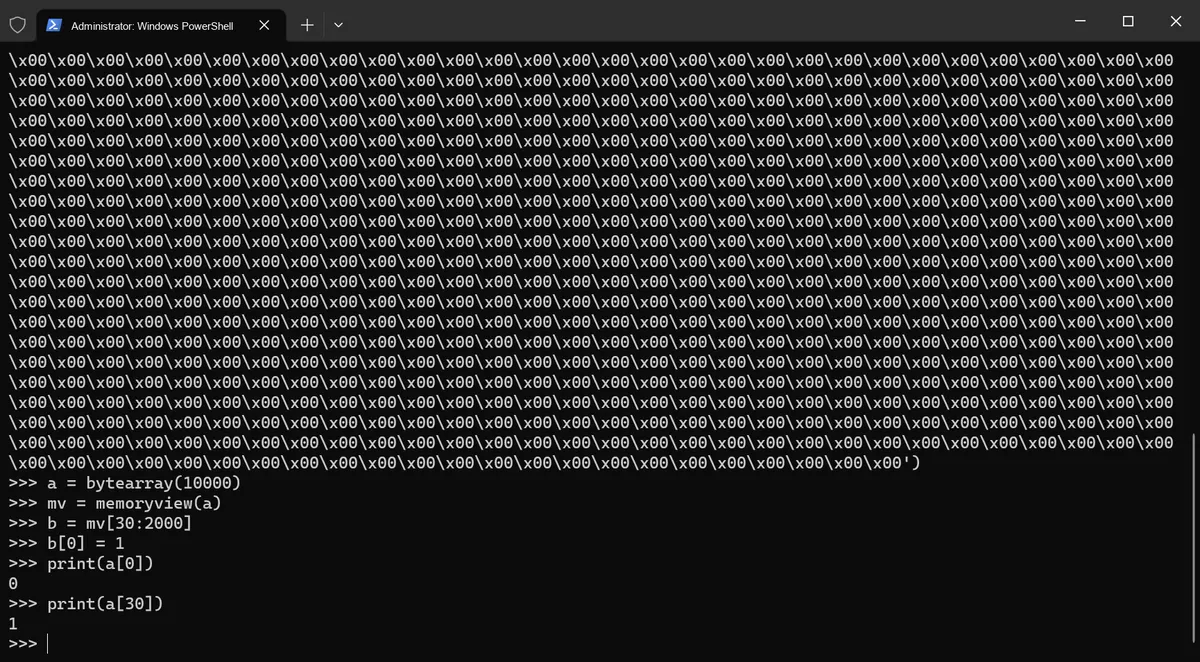
Here, it should be noted that memoryview only supports objects implementing the buffer protocol (bytearray, array, bytes), and does not support lists (lists store object references rather than contiguous data).
After mastering the above basics, you can then understand these advanced concepts of embedded MicroPython:
- Garbage Collection (
GC): MicroPython automatically cleans up objects in the heap that are no longer referenced, and this process will block the program. We can manually callgc.collect ()to control the timing of cleanup and avoid triggering it in performance-critical sections. - native/viper code emitter: compile Python code into ARM-Thumb machine code (rather than bytecode), whose execution speed is much faster than interpreted execution (the speed of native is twice that of bytecode, while viper is more aggressive, supports pointer operations, and is close to the speed of C language).
- Direct register manipulation: bypasses MicroPython's hardware abstraction layer (such as
machine.Pin), directly reads and writes the register addresses of the chip, eliminating the extra overhead of method calls (suitable for high-frequency hardware operations). - mpy-cross: A MicroPython cross-compiler that pre-
. pyscripts on a computer into. mpybytecode, which reduces the compile overhead on the device and speeds up script loading.
2.2.1.2 Performance Bottlenecks of MicroPython
The performance bottlenecks of MicroPython mainly stem from three core aspects: the overhead of heap memory allocation and garbage collection (GC), the overhead of interpreted execution of Python bytecode, and inefficient operation/hardware operation methods.
Therefore, we can carry out optimization from the following aspects:
- Memory and Object Optimization (Highest Priority, Lowest Cost): Address the overhead issues of heap allocation and GC, which is the most common performance bottleneck in MicroPython embedded scenarios.
- Code Execution Efficiency Optimization (Medium Priority): Improve the running speed of the code itself, with optimizations ranging from the bytecode level to the machine code level.
- Computation and hardware optimization (lowest priority, suitable for performance-critical scenarios): Utilizing hardware features to reduce inefficient computations/operations is the ultimate optimization approach.
2.2.2 Memory and Object Optimization
The core of this type of optimization is to "avoid dynamically creating objects at runtime and reduce heap allocation as much as possible, thereby lowering the trigger frequency and time consumption of GC", which is the primary step for Performance optimization of embedded MicroPython.
2.2.2.1 Pre-allocated Memory and Fixed Object Size
The object is created only once (e. g., instantiated in the class constructor), and its size is not allowed to grow dynamically (e. g., list append, adding new Attribute–Value Pairs to a dictionary). Especially for buffers (such as buffers for serial communication), pre-allocation and reuse are required.
We can use readinto () instead of read ()(read () allocates a new buffer each time, while readinto () reads data into an existing buffer).
Take the serial port buffer as an example:
from machine import UART, Pin

# 1. Preallocate the buffer (create it only once, avoiding dynamic allocation)
buf = bytearray(64)  # Preallocate a 64-byte buffer

# Initialize UART
uart = UART(0, baudrate=9600, tx=Pin(0), rx=Pin(1))

# 2. Use readinto() to read into the preallocated buffer (no new allocation)
while True:
    if uart.any():
        # Data is read into buf, returns the number of bytes read
        n = uart.readinto(buf)
        # Comparison: uart.read(64) creates a new bytes object each time, triggering heap allocation
        print("recv data:", buf[:n])
2.2.2.2 Use arrays instead of lists + memoryview to avoid data copying
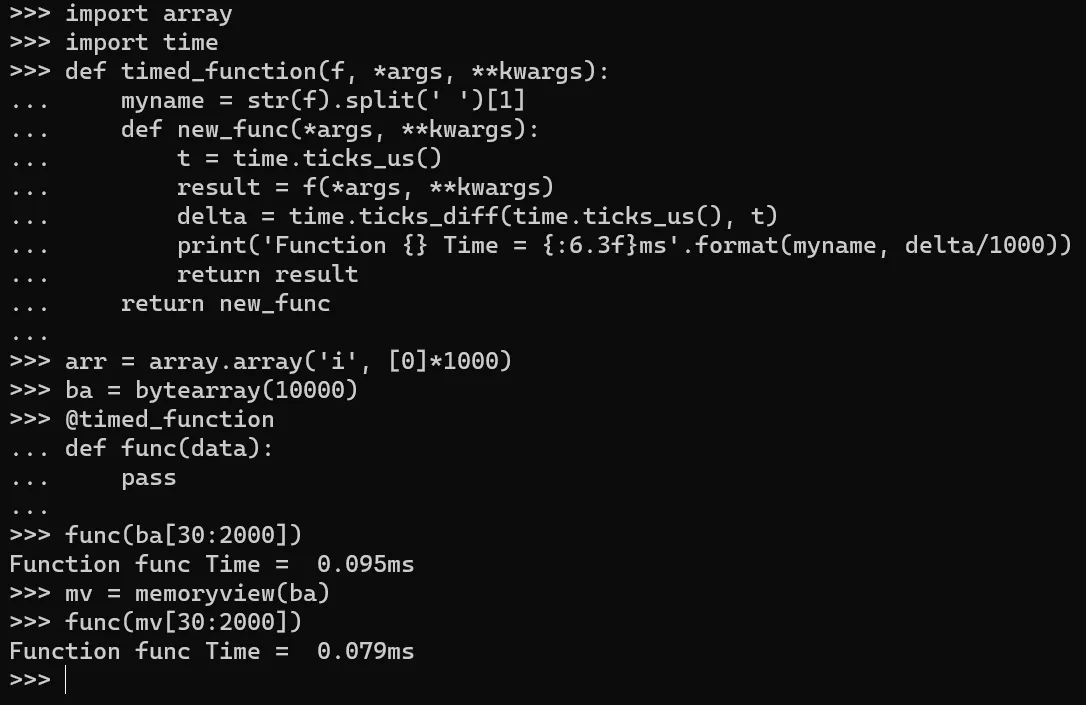
Lists store object references, with non-contiguous memory, and dynamic growth will trigger heap allocation;array module (or bytearray) stores contiguous primitive type data, delivering higher performance after pre-allocation; meanwhile, slice operations (e. g., ba[30:2000]) will create data copies and trigger heap allocation; using memoryview enables direct passing of memory pointers with no copy overhead.
import array
import time

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func

# 1. Use array instead of list (stores integers, contiguous memory)
# Preallocate an array of 1000 int elements
arr = array.array('i', [0]*1000)
# 2. Use memoryview to avoid slice copies
# Large bytearray
ba = bytearray(10000)

# Direct slicing: creates a copy, triggering a ~2K heap allocation
@timed_function
def func(data):
    pass

# Test slice copy (slow and uses memory)
func(ba[30:2000])

# Using memoryview: allocates only a small object, no data copy
mv = memoryview(ba)
# What is passed is a memory pointer, no allocation
func(mv[30:2000])
The terminal output is as follows:
2.2.2.3 Cached Object Reference
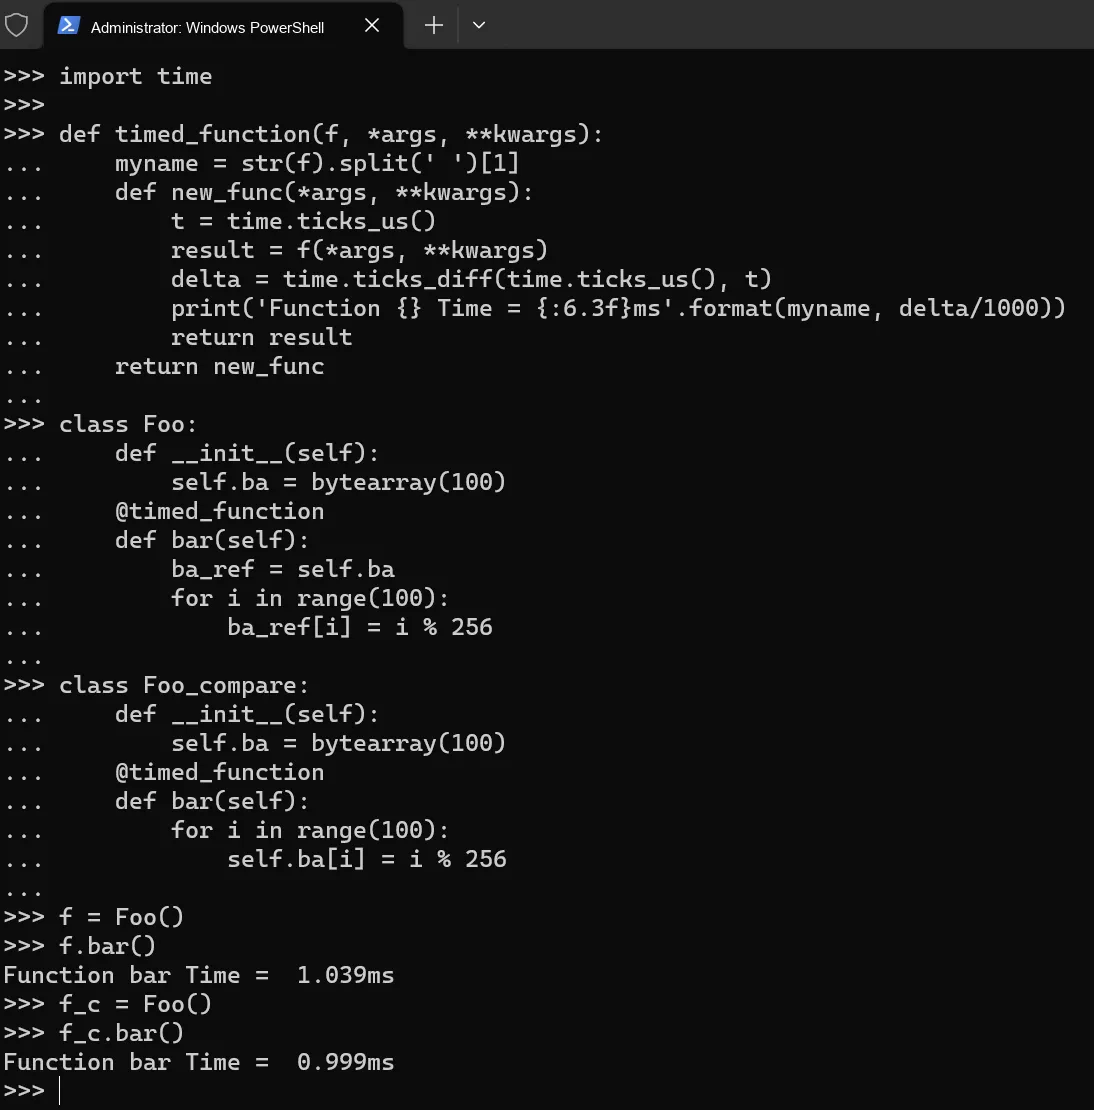
Cache frequently accessed objects (such as self.ba, obj_display.framebuffer) into local variables to avoid attribute lookup on every access — attribute lookup involves dictionary operations, which is time-consuming and may trigger memory allocation.
import time

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func

class Foo:
    def __init__(self):
        self.ba = bytearray(100)
    @timed_function
    def bar(self):
        ba_ref = self.ba
        for i in range(100):
            ba_ref[i] = i % 256

class Foo_compare:
    def __init__(self):
        self.ba = bytearray(100)
    @timed_function
    def bar(self):
        for i in range(100):
            self.ba[i] = i % 256

# Test
f = Foo()
f.bar()

f_c = Foo()
f_c.bar()
Click to run, and the terminal outputs the following:
2.2.2.4 Manual Garbage Collection Control
Call gc.collect () manually on a regular basis to trigger GC, so as to prevent GC from being triggered randomly in performance-critical code segments (manual GC allows timing control, and the time cost of frequent minor GCs is far lower than that of a single major GC).
import gc
import time

# Enable GC (enabled by default, can be disabled/enabled manually)
gc.enable()
# Before a performance-critical loop, trigger GC manually
# Clean up memory in advance, takes about 1ms
gc.collect()

# Performance-critical code section
start = time.ticks_us()
for i in range(10000):
    pass
end = time.ticks_us()

print(f"耗时:{utime.ticks_diff(end, start)/1000}ms")
# Trigger GC periodically in non-critical sections
# gc.collect()
2.2.2 Optimization of Code Execution Efficiency
Such optimizations, built on the basis of memory optimization, further boost the execution speed of code, with optimizations implemented from the bytecode level all the way to the machine code level.
2.2.2.1 Declare constants using const ()
const () replaces identifiers with values (completed at compile time), avoiding runtime dictionary lookups; this delivers remarkable optimization effects, especially for constants used in loops.
from micropython import const
import time

# Declare constants (replaced with values at compile time)
MAX_COUNT = const(100000)
# Binary constants are also supported
PIN_BIT = const(1 << 2)

MAX_COUNT_NOT_USE_CONST = 100000

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func

@timed_function
def use_const():
    total = 0
    for i in range(MAX_COUNT):
        total += i
    return total

# Comparison: without const(), every access looks up a dictionary, which takes longer
@timed_function
def no_const():
    global MAX_COUNT_NOT_USE_CONST
    total = 0
    for i in range(MAX_COUNT_NOT_USE_CONST):
        total += i
    return total

result1 = use_const()
result2 = no_const()
The running result in the terminal is as follows:
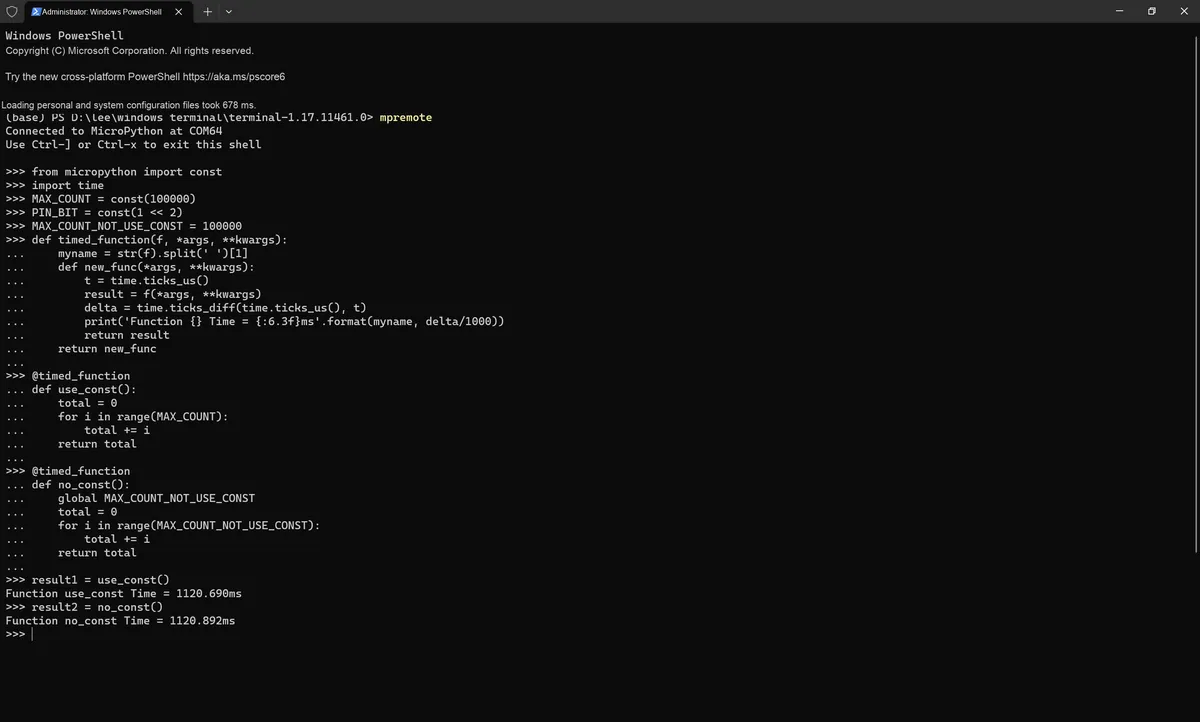
We can see that the running time of the two is actually almost the same, because in the REPL, the code is executed in an interpreted manner, while const 's real advantage only becomes obvious in pre-compiled bytecode.
2.2.2.2 mpy-cross compile bytecode
Use mpy-cross on a computer to. py scripts to pre-compile them into. mpy bytecode, then upload it to the device.
We can use the pip command to install the mpy-cross tool:
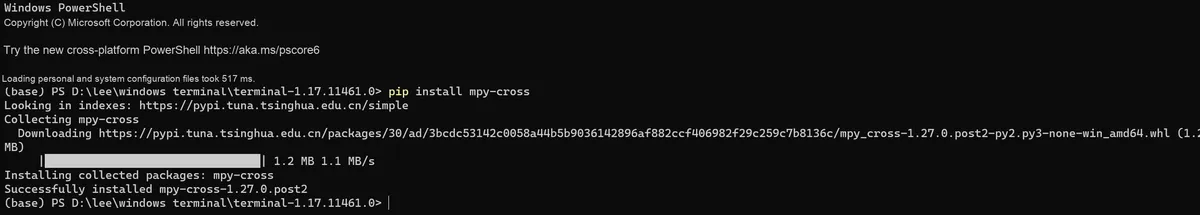
Then, use the following command to MicroPython 's py files compile into mpy files:
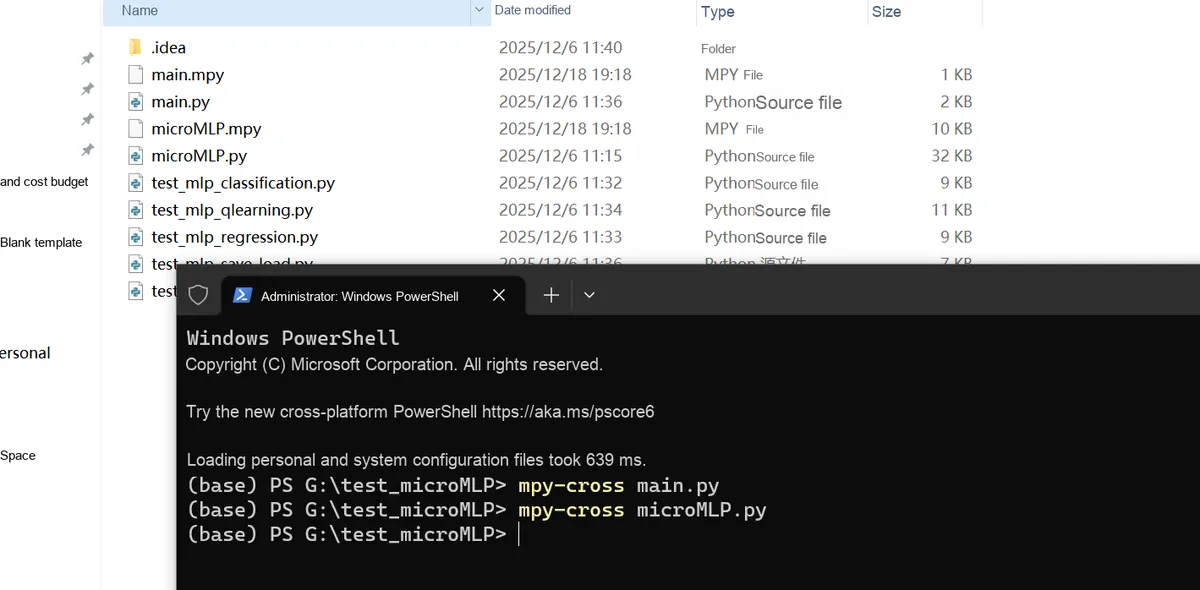
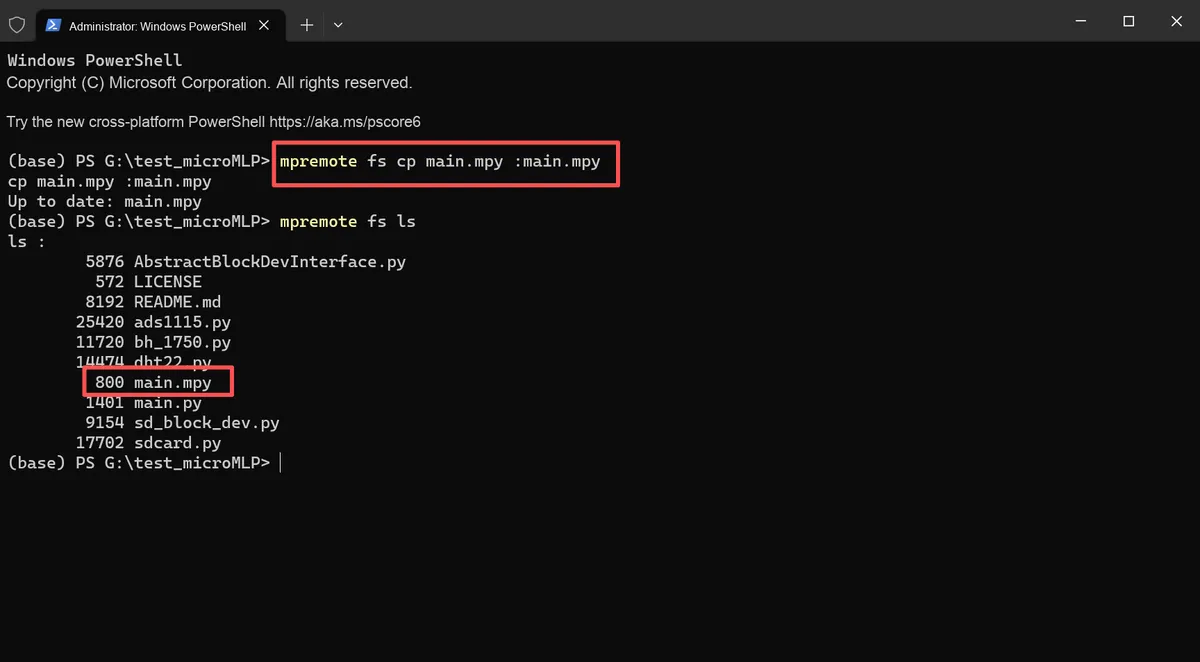
We can see that the compiled mpy file is smaller. Next, just use the mpremote tool to deploy it to the device side.
2.2.2.3 Using a Code Transmitter
When MicroPython compiles code, it processes each function individually (classes are functions, as are lambdas and list comprehensions). Functions emerge from the parsing phase and then enter the compiler, which passes the Python function three times:
- In the first phase, the compiler collects information about variables and their scopes (local or global), and identifies the emitter type by looking for special types of function decorators;
- In the second phase, it calculates the stack usage and code offsets;
- In the third phase, codes are transmitted by the required transmitters.
Currently, there are four types of code transmitters:
- Bytecode emitter: By default, a function uses the bytecode emitter, and the generated bytecode runs on MicroPython's built-in virtual machine. The virtual machine is very simple: it decodes each bytecode (along with its parameters, if any) and calls the corresponding C runtime function;
- native code emitter: The native code emitter takes each bytecode and converts it into equivalent ARM-Thumb machine code. Such functions use the ordinary C stack to store local variables and directly call C runtime functions; however, note that they cannot be used in context managers (with statements) and generators, and if raise is used, arguments must be provided;
- Viper Code Emitter: compile into optimized machine code, supports pointer operations, and its speed is close to that of C language (with more compatibility restrictions).
- Inline assembler: Not to be discussed for now, please refer to the link http://www.86x.org/en/latet/reference/asm_thumb2_index.html .
2.2.2.3.1 native code emitter
The native code emitter takes each bytecode and converts it to equivalent ARM-Thumb machine code. Such functions use the standard C stack to store local variables and directly call C runtime functions.
The native code emitter is invoked via a function decorator:
@micropython.native
def foo(self, arg):
    buf = self.linebuf # Cached object
    # code
The current implementation of the native code emitter has certain limitations:
- Context managers (the `with` statement) are not supported
- Generators are not supported
- If raise is used, an argument must be provided
The tradeoff for improved performance (roughly twice that of bytecode) is an increase in the size of the compile code.
2.2.2.3.2 Viper Code Transmitter
The optimizations discussed above involve standard-compliant Python code. The Viper code emitter is not fully compliant. It supports special Viper native data types in pursuit of performance. Integer processing is non-compliant because it uses machine words: arithmetic on 32-bit hardware is performed modulo 2**32.
The Viper code emitter emits ARM-Thumb machine code for each bytecode and further optimizes certain operations, such as integer arithmetic. For the addition of two integers, the Viper emitter does not call the C runtime function rt_binary_op; instead, it emits the machine instruction "adds" to directly add the two numbers. This is significantly faster than calling rt_binary_op. It is invoked using a decorator:
@micropython.viper
def foo(self, arg: int) -> int:
    # code
Viper supports its own set of types, namely int, uint (unsigned integer), ptr, ptr8, ptr16 and ptr32:
- ptr Pointer to the object
- ptr8 points to one byte
- ptr16 points to a 16-bit half-word
- ptr32 points to a 32-bit machine word
Here, let's test integer accumulation with heavy computational load:
import time
import micropython

def timed_function(name):
    def decorator(f):
        def new_func(*args, **kwargs):
            t = time.ticks_us()
            result = f(*args, **kwargs)
            delta = time.ticks_diff(time.ticks_us(), t)
            print('Function {} Time = {:6.3f}ms'.format(name, delta/1000))
            return result
        return new_func
    return decorator

# Regular Python function: 1 million accumulations (function name 'normal_add_loop' specified manually)
@timed_function('normal_add_loop')
def normal_add_loop(n: int) -> int:
    total = 0
    for i in range(n):
        total += i * 2 + 5
    return total

# Viper-optimized function: same amount of computation (function name 'viper_add_loop' specified manually)
@timed_function('viper_add_loop')
@micropython.viper
def viper_add_loop(n: int) -> int:
    total = 0
    for i in range(n):
        total += i * 2 + 5
    return total

# Call test (1 million operations, normal timing output)
normal_add_loop(1000000)
viper_add_loop(1000000)
Two functions perform exactly the same 1 million integer operations (i*2+ 5 accumulation), but normal_add_loop is executed purely by interpretation, while viper_add_loop is executed directly as machine code. The terminal output results are as follows:
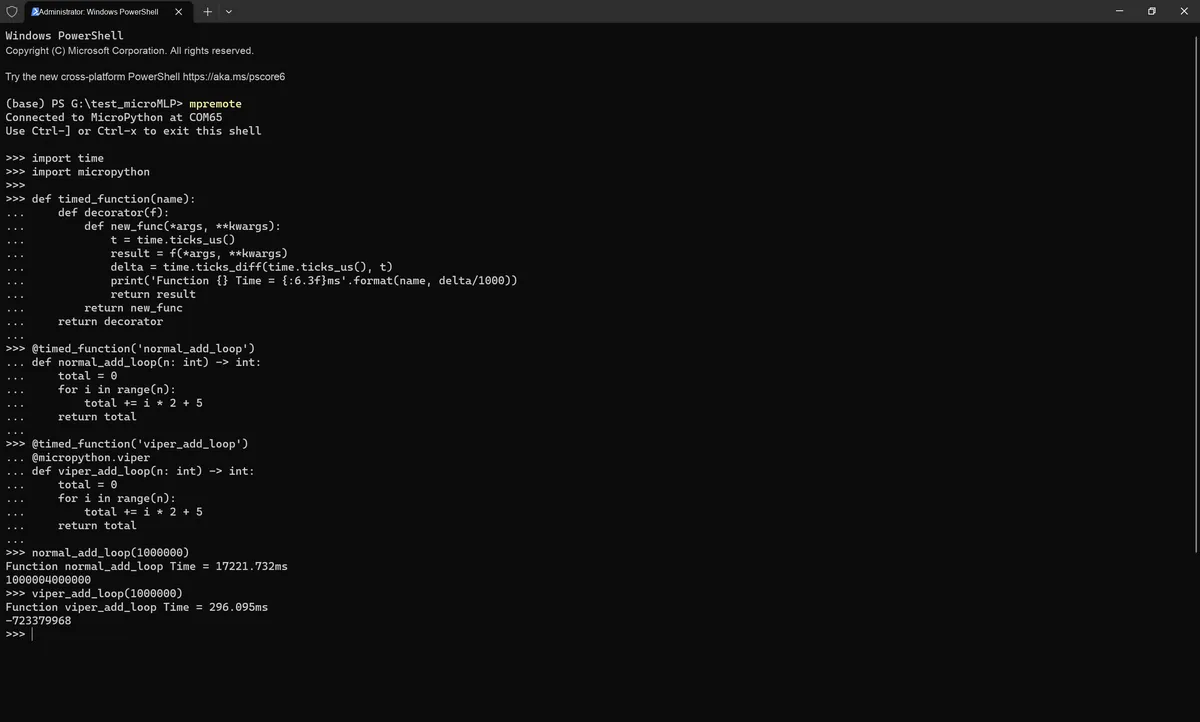
We conducted tests on the Raspberry Pi Pico, and the time consumption of normal_add_loop is dozens of times that of viper_add_loop.
Viper has two key limitations:
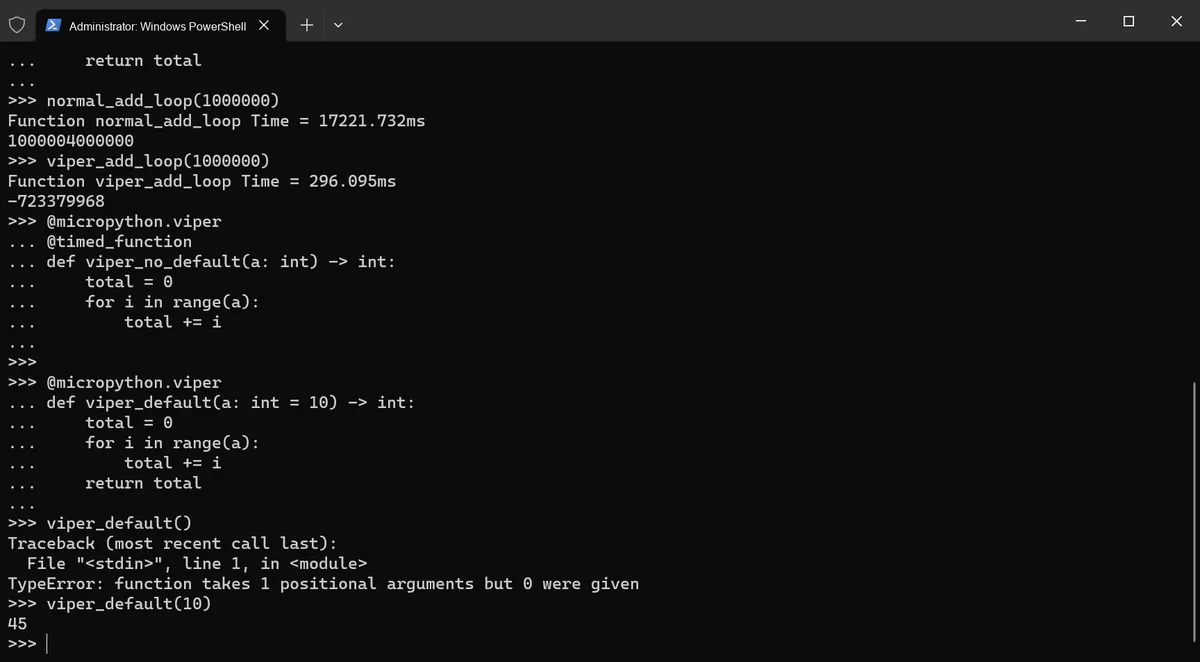
- Default parameters are not allowed: function parameters cannot be set with
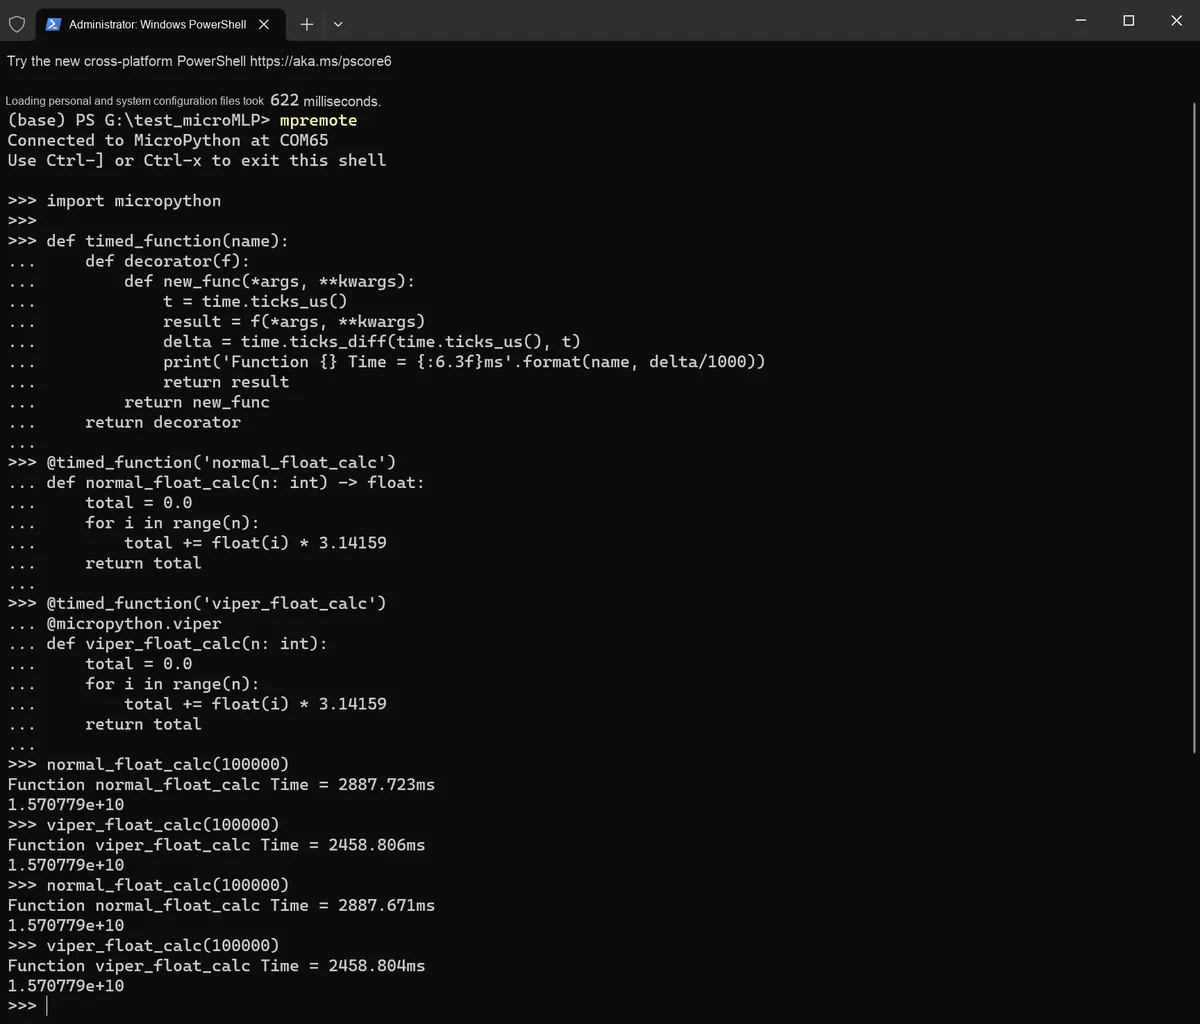
a: int = 10as the default value, otherwise an error will be reported. - Floating-point operations are supported but not optimized: The time consumption of floating-point calculation is almost the same as that of an ordinary Python function, because Viper does not generate optimized machine code for floating-point operations.
import micropython
# Incorrect example (running in the REPL raises an error: Viper does not support default arguments)
# @micropython.viper
# def viper_default(a: int = 10) -> int:
#     total = 0
#     for i in range(a):
#         total += i
#     return total

# Correct example (no default arguments, 1 million operations, timed)
@micropython.viper
@timed_function
def viper_no_default(a: int) -> int:
    total = 0
    for i in range(a):
        total += i
    return total

# Call test
viper_no_default(1000000)
The running results are as follows:
Let's test the floating-point operations of the function compiled by Viper and ordinary functions again:
import micropython

def timed_function(name):
    def decorator(f):
        def new_func(*args, **kwargs):
            t = time.ticks_us()
            result = f(*args, **kwargs)
            delta = time.ticks_diff(time.ticks_us(), t)
            print('Function {} Time = {:6.3f}ms'.format(name, delta/1000))
            return result
        return new_func
    return decorator

# Regular function: 100,000 floating-point multiply-accumulates
@timed_function('normal_float_calc')
def normal_float_calc(n: int) -> float:
    total = 0.0
    for i in range(n):
        total += float(i) * 3.14159
    return total

# Viper function: same 100,000 floating-point operations (no optimization)
@timed_function('viper_float_calc')
@micropython.viper
def viper_float_calc(n: int):
    total = 0.0
    for i in range(n):
        total += float(i) * 3.14159
    return total

# Call test (timing results are almost identical)
normal_float_calc(100000)
viper_float_calc(100000)
The running results are as follows:
Viper's pointer types (ptr8/ptr16/ptr32) are used to directly access contiguous memory (such as bytearray) without boundary checking, and support single-element access via subscript (slicing is not supported). A key optimization technique is: to place the operation of converting an object to a pointer at the beginning of the function rather than inside a loop, as the conversion takes several microseconds, which will be amplified in large loops.
The advantage of pointers is particularly prominent in the scenario of traversing large arrays, which is far faster than array access in ordinary Python.
import micropython

def timed_function(name):
    def decorator(f):
        def new_func(*args, **kwargs):
            t = time.ticks_us()
            result = f(*args, **kwargs)
            delta = time.ticks_diff(time.ticks_us(), t)
            print('Function {} Time = {:6.3f}ms'.format(name, delta/1000))
            return result
        return new_func
    return decorator

# Prepare a bytearray of length 10,000 (large array)
ba = bytearray(10000)
for i in range(10000):
    ba[i] = i % 256

# Regular function: iterate over 100,000 bytearray accesses, accumulate values
@timed_function('normal_bytearray_access')
def normal_bytearray_access(ba: bytearray) -> int:
    total = 0
    for i in range(10000):
        total += ba[i]
    return total

# Viper function: access via ptr8 pointer, accumulate values (conversion placed at the start)
@timed_function('viper_ptr8_access')
@micropython.viper
def viper_ptr8_access(ba) -> int:
    buf = ptr8(ba)
    total = 0
    for i in range(10000):
        total += buf[i]
    return total

# Call test (pointer access is much faster than regular access)
normal_bytearray_access(ba)
viper_ptr8_access(ba)
The terminal output is as follows:
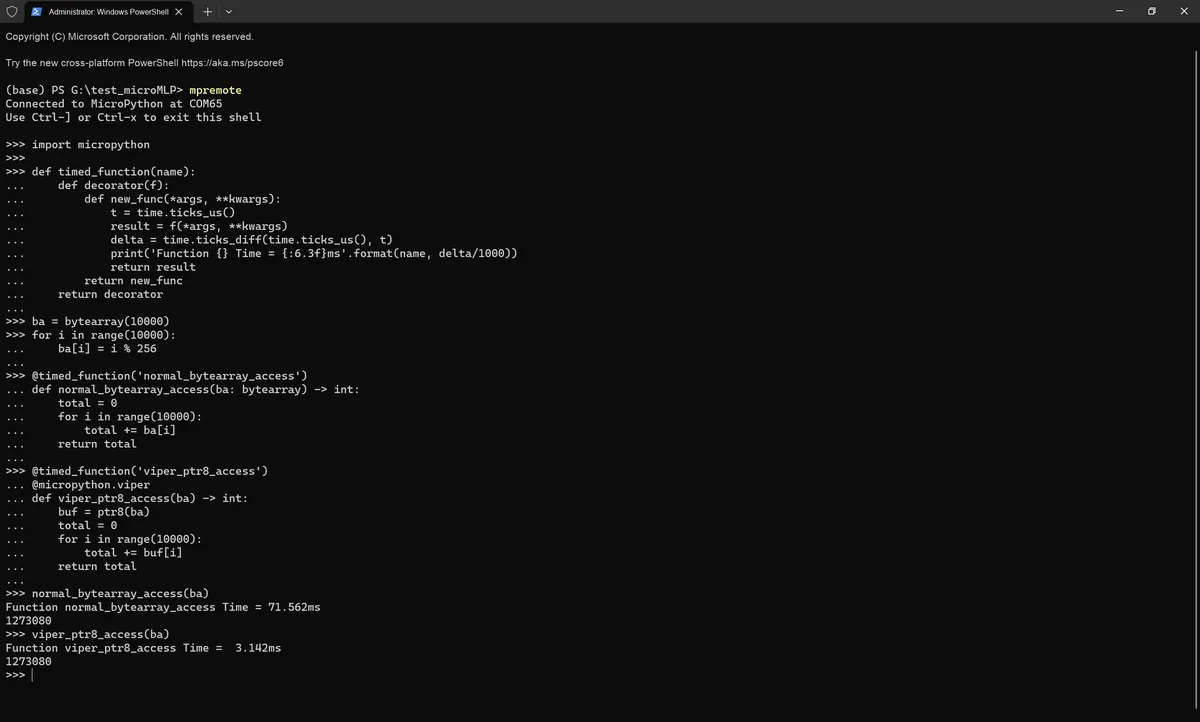
viper_ptr8_access takes only one-thirtieth of the time of normal_bytearray_access: the ba[i]in a normal function needs to go through steps such as Python's boundary check and object attribute lookup; Viper's buf[i]directly calculates the memory address and accesses the byte, with no additional overhead.
Next, let's compare the difference between performing pointer operations on the converted object inside a loop and doing so at the beginning:
import micropython

def timed_function(name):
    def decorator(f):
        def new_func(*args, **kwargs):
            t = time.ticks_us()
            result = f(*args, **kwargs)
            delta = time.ticks_diff(time.ticks_us(), t)
            print('Function {} Time = {:6.3f}ms'.format(name, delta/1000))
            return result
        return new_func
    return decorator

# Prepare a bytearray of length 10,000 (large array)
ba = bytearray(10000)
for i in range(10000):
    ba[i] = i % 256

# Viper function: repeated ptr8 conversion inside the loop (inefficient)
@timed_function('viper_bad_convert')
@micropython.viper
def viper_bad_convert(ba) -> int:
    total = 0
    for i in range(10000):
        buf = ptr8(ba)
        total += buf[i]
    return total

# Viper function: one-time ptr8 conversion at the start (efficient)
@timed_function('viper_good_convert')
@micropython.viper
def viper_good_convert(ba) -> int:
    buf = ptr8(ba)
    total = 0
    for i in range(10000):
        total += buf[i]
    return total

# Call test (the inefficient version takes much longer than the efficient one)
viper_bad_convert(ba)
viper_good_convert(ba)
The running results are as follows:
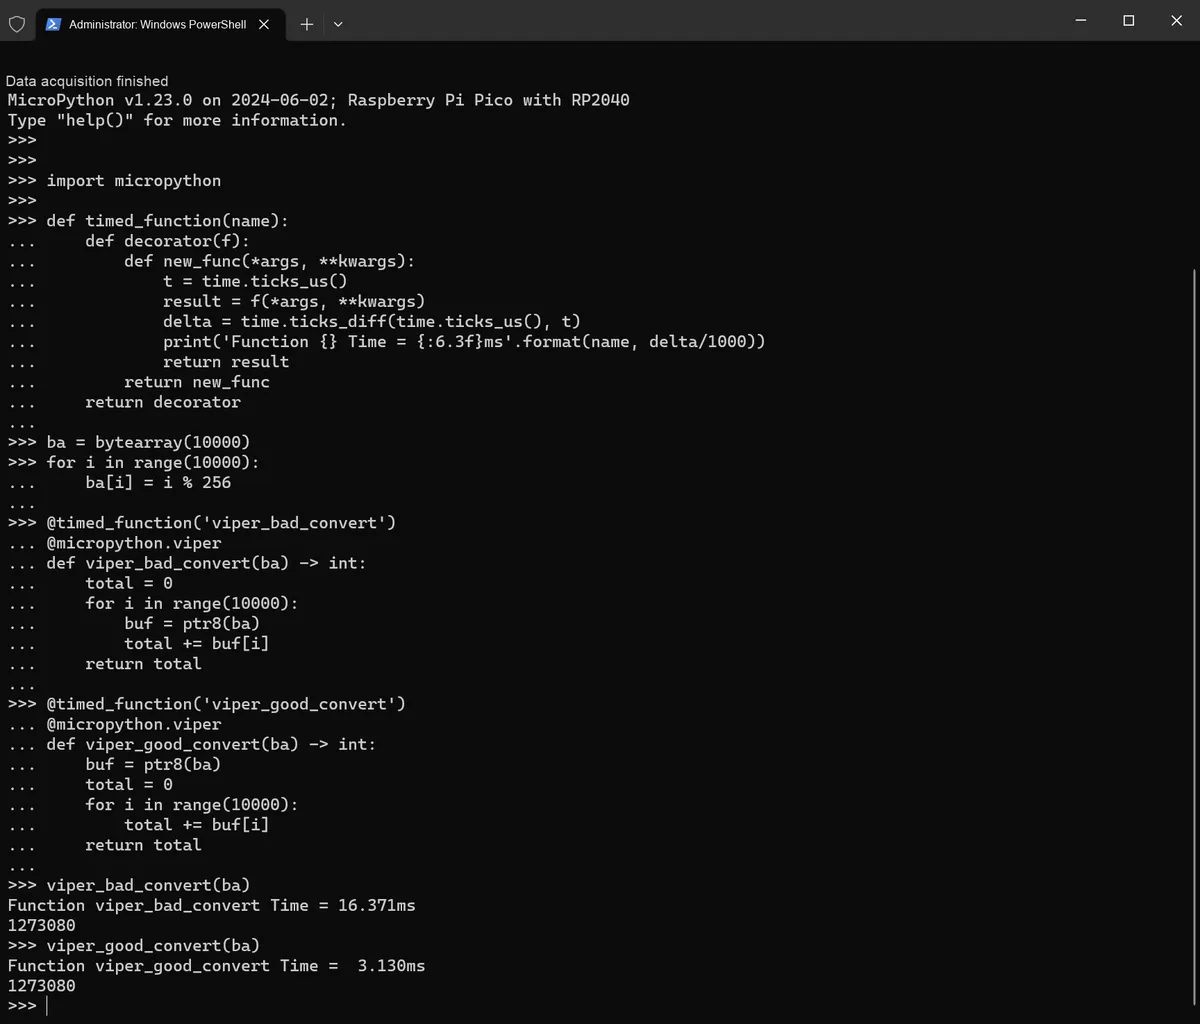
viper_bad_convert performs a type conversion via ptr8 (ba) in each of 1 million loops (each conversion takes several microseconds, leading to significant accumulated time cost);viper_good_convert only performs the conversion once at the start, thus eliminating redundant overhead.
Viper's integers operate at the machine word level, with arithmetic operations executed modulo 2**32 on 32-bit hardware (truncation occurs upon overflow); this is a trade-off where compatibility is sacrificed for performance, and this characteristic becomes more pronounced under heavy computational loads.
2.2.3 Operation and hardware Optimization
2.2.3.1 Replace floating-point operations with integer operations
Chips without an FPU (floating-point coprocessor) execute floating-point operations extremely slowly, so integer operations are used in performance-critical sections, and conversion to floating-point numbers is only done in non-critical sections.
from machine import ADC, Pin
import array

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func

# 1. Pure integer operations: preallocated array + ADC readings (no floating point)
# Preallocate an array of 100 int elements (contiguous memory, no dynamic allocation)
# Pure integer operation: read 16-bit integer ADC values
@timed_function
def adc_read_integer():
    adc_data = array.array('i', [0]*100)
    adc = ADC(Pin(26))

    for i in range(100):
        adc_data[i] = adc.read_u16()
    return adc_data

# 2. With floating-point operations: integer readings + floating-point conversion (voltage calculation)
# Step 1: integer readings (same as above)
# Step 2: floating-point operation converts to voltage (reading/65535*3.3)
@timed_function
def adc_read_float():
    adc_data = array.array('i', [0]*100)
    adc = ADC(Pin(26))

    for i in range(100):
        adc_data[i] = adc.read_u16()

    voltage_data = [x/65535*3.3 for x in adc_data]
    return voltage_data

# Run the test, compare elapsed time
print("=== ADC读数性能对比 ===")
integer_data = adc_read_integer()
float_data = adc_read_float()

# Print the first 5 voltage values (verify functionality)
print("\n前5个电压值:", float_data[:5])
Terminal execution:
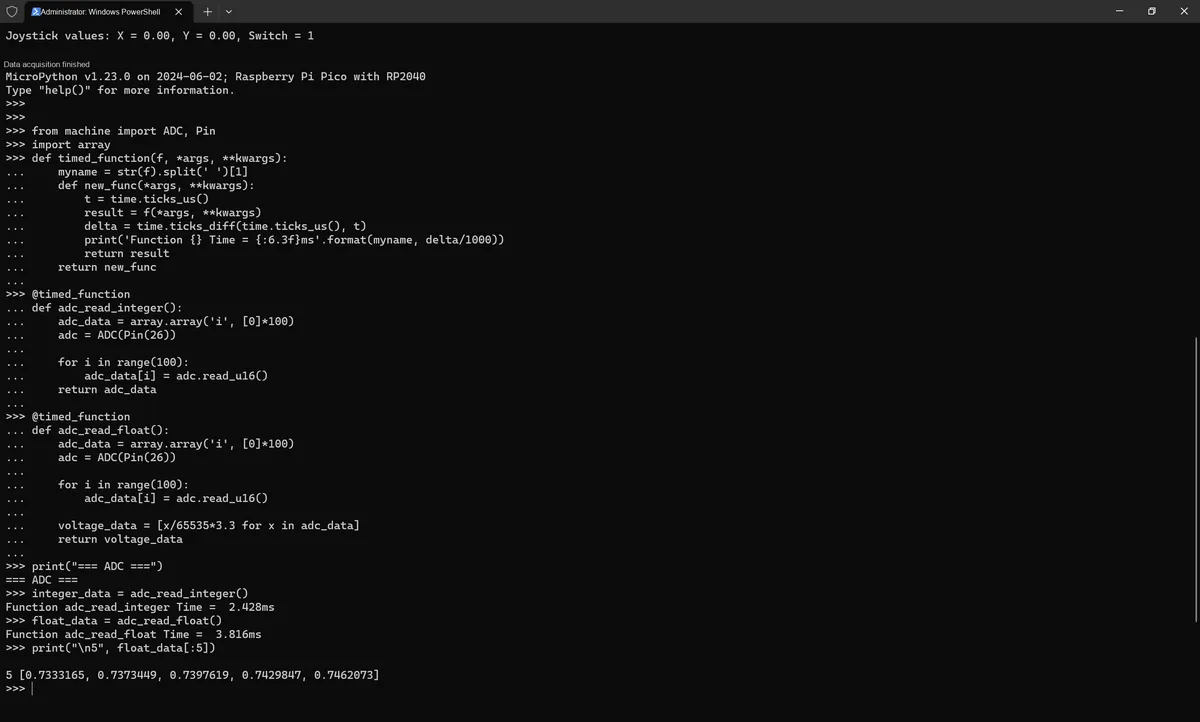
We can see that floating-point operations take more time than pure integer operations.
2.2.3.2 Direct Register Read/Write
Bypass MicroPython's hardware abstraction layer to directly read and write chip registers, eliminating the overhead of method calls (e. g. fast LED blinking, high-frequency GPIO operations).
from machine import Pin, mem32
import time
from micropython import const

def timed_function(f, *args, **kwargs):
    myname = str(f).split(' ')[1]
    def new_func(*args, **kwargs):
        t = time.ticks_us()
        result = f(*args, **kwargs)
        delta = time.ticks_diff(time.ticks_us(), t)
        print('Function {} Time = {:6.3f}ms'.format(myname, delta/1000))
        return result
    return new_func

# --------------------------
# Configure SIO registers (Raspberry Pi Pico only)
# --------------------------
# SIO module base address (fixed on RP2040)
# SIO GPIO core registers (correct addresses, fixing the earlier error)
SIO_BASE = const(0xD0000000)
# Write all GPIO output values at once
GPIO_OUT = SIO_BASE + 0x010
# Atomic GPIO set
GPIO_OUT_SET = SIO_BASE + 0x014
# Atomic GPIO clear
GPIO_OUT_CLR = SIO_BASE + 0x018
# Atomic GPIO toggle
GPIO_OUT_XOR = SIO_BASE + 0x01C
# Atomically set GPIO as output mode# Bit mask for GPIO25 (onboard LED) (bit25 corresponds to GPIO25)
GPIO_OE_SET = SIO_BASE + 0x024

# Initialization: set GPIO25 to output mode (run only once, atomic operation)
PIN25_MASK = const(1 << 25)
mem32[GPIO_OE_SET] = PIN25_MASK

# Initialize the Pin object (run only once)
led_pin = Pin(25, Pin.OUT)

# Method 1: operate GPIO25 with regular machine.Pin (hardware abstraction layer, has overhead)
@timed_function
def led_pin_loop(loop_count):
    for _ in range(loop_count):
        led_pin.value(1)
        led_pin.value(0)

# Method 2: operate GPIO25 with SIO registers (no abstraction layer, extremely efficient)
@timed_function
def led_sio_set_clr_loop(loop_count):
    set_reg = GPIO_OUT_SET
    clr_reg = GPIO_OUT_CLR
    mask = PIN25_MASK
    for _ in range(loop_count):
        mem32[set_reg] = mask
        mem32[clr_reg] = mask

# Test running speed
loop_count = 1000

led_pin_loop(loop_count)
led_sio_set_clr_loop(loop_count)
The running results are as follows:
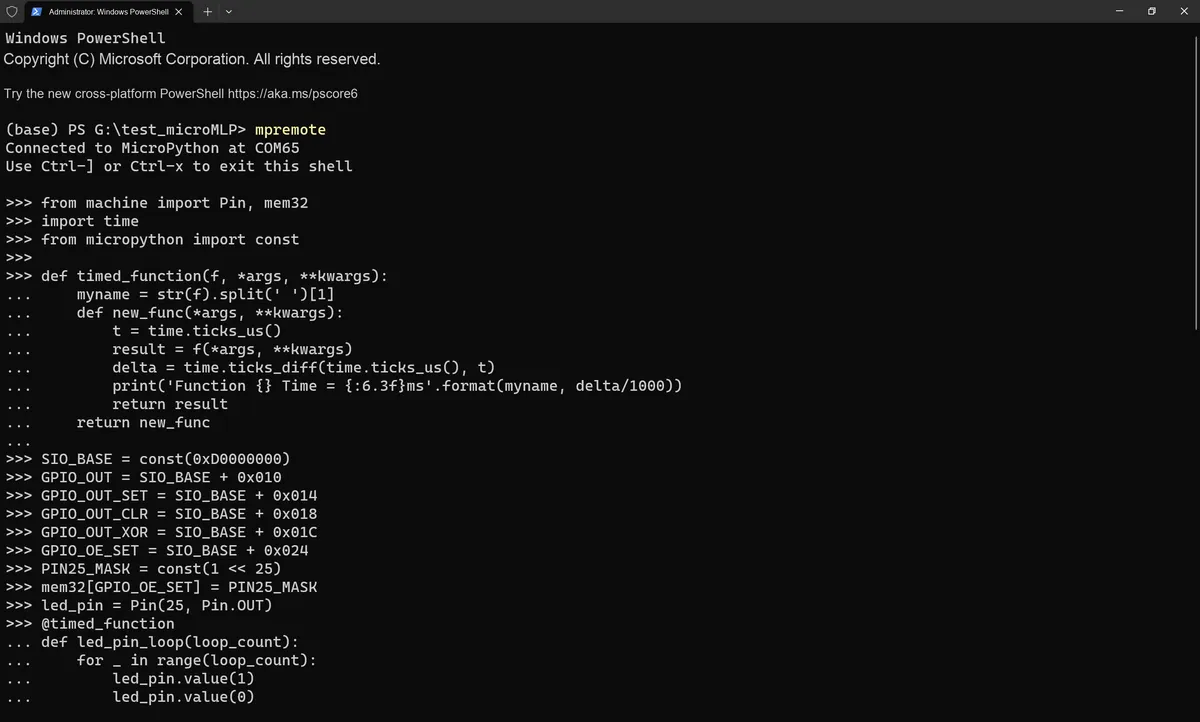
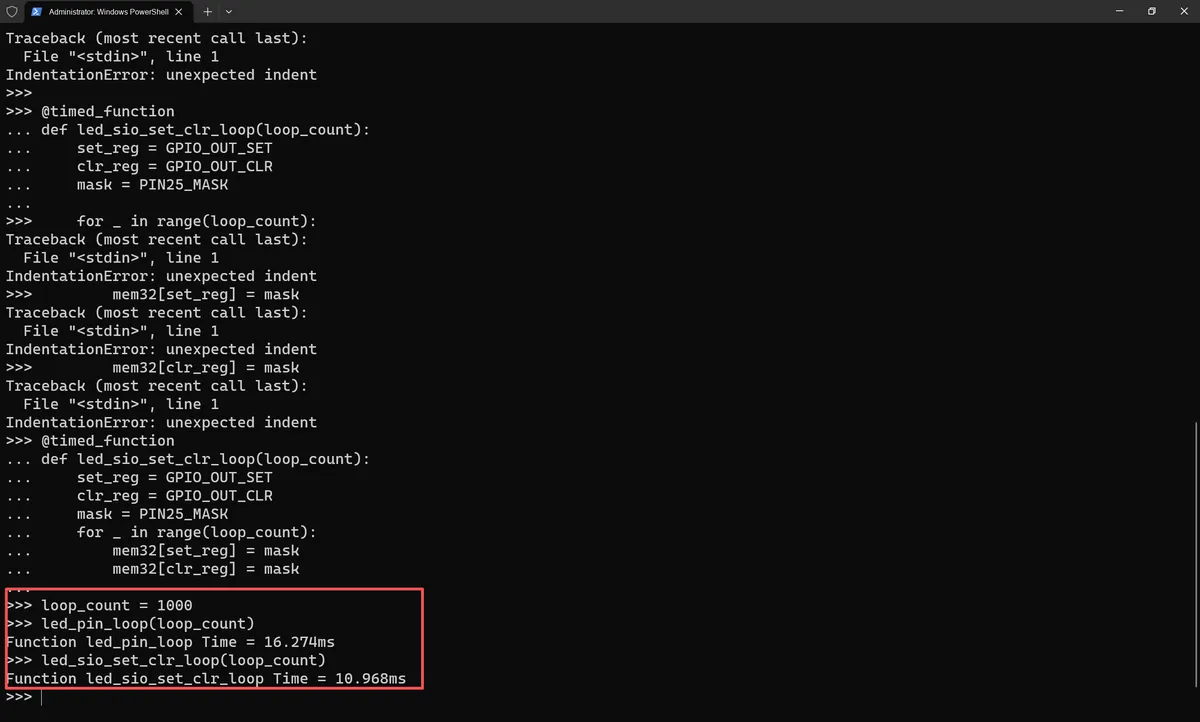
As can be seen, in the SIO loop function, GPIO_OUT_SET, GPIO_OUT_CLR, and PIN25_MASK are cached into local variables, which reduces the overhead of global variable lookup and makes the performance advantage of SIO more prominent.
2.2.3.3 DMA-related Operations
In scenarios involving arithmetic and hardware data interaction (such as batch ADC data acquisition, high-frequency GPIO signal output, and sensor data stream reading), the CPU often needs to spend a large amount of time performing data transmission operations (such as reading data from peripheral registers to memory and writing arithmetic results to GPIO registers), which preempts the resources required for arithmetic operations.The DMA (Direct Memory Access) controller of the RP2040 can independently complete bulk data transfers between memory and peripherals/registers without CPU intervention, and its core optimization value lies in: freeing the CPU from tedious data transfer tasks and allowing it to focus on core computing logic.
From the perspectives of development and performance, MicroPython only provides relatively basic support for RP2040 DMA, which can only implement simple batch data transmission; in contrast, C language (Pico SDK) allows full configuration of the DMA's transmission mode, trigger conditions and data processing rules. Combined with direct register operations, it can achieve seamless optimization of arithmetic operations and hardware data interaction, making it the optimal choice for high-throughput and low-latency scenarios.
III. Optimization Experiment
3.1 Optimization of LCD Screen
For this, you may refer to:
08 SPI Serial Peripheral Interface - Document Tutorial Draft
3.2 DMA-related Optimization
For this, you may refer to:
19 DMA Direct Memory Access - Document Tutorial Draft
References
https://docs.micropython.org/en/latest/reference/speed_python.html